dnn_semantic_segmentation
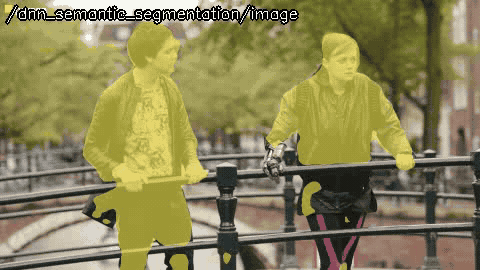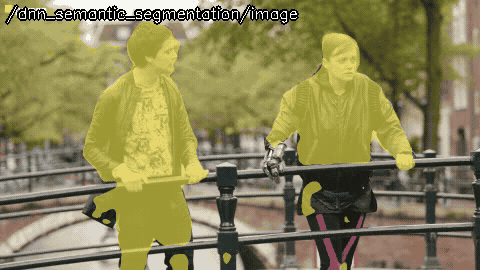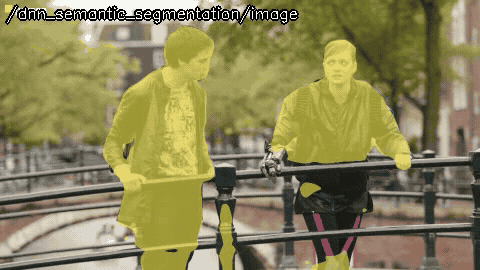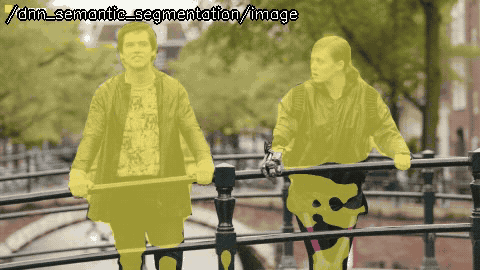
Semantic segmentation with a DNN model, e.g. PP-HumanSeg.
Semantic segmentation, by default of the persons with PP-HumanSeg of opencv_zoo, or with a model whose output is the scores of the classes for each pixel (1 x classes x height x width), e.g. FCN, DeepLab, ENet.
opencv_apps |
3.0.0 and later |
|---|---|
ROS |
ROS One, jazzy, kilted, lyrical and later |
OpenCV |
OpenCV 4.5.4 or later |
Group |
Segmentation, the nodes of which publish the mask or label image, |
Usage
# ROS 2
ros2 launch opencv_apps dnn_semantic_segmentation.launch.xml image:=/camera/image_raw debug_view:=false
# ROS 1
roslaunch opencv_apps dnn_semantic_segmentation.launch image:=/camera/image_raw debug_view:=false
Try it with the demo video
Download the input video of the demo above, publish it as image with image_publisher, and run the node on it, in the terminals:
wget https://ros-perception.github.io/opencv_apps/media/clips/tos_bridge.mp4
# terminal 1: publish the video as image in a loop
ros2 run image_publisher image_publisher_node tos_bridge.mp4 --ros-args -p publish_rate:=10.0 -r image_raw:=image
# terminal 2: run the node
ros2 launch opencv_apps dnn_semantic_segmentation.launch.xml image:=image
# terminal 3: view the result
ros2 run rqt_image_view rqt_image_view /dnn_semantic_segmentation/image
In ROS 1:
# terminal 1
rosrun image_publisher image_publisher tos_bridge.mp4 _publish_rate:=10 __name:=camera
# terminal 2
roslaunch opencv_apps dnn_semantic_segmentation.launch image:=camera/image_raw
See Credits of the demo videos for the license of the video.
Subscribed topics
Topic |
Type |
|---|---|
|
|
Published topics
Topic |
Type |
|---|---|
|
|
|
|
Parameters
See also the common parameters.
Name |
Type |
Default (range) |
Changed at run time |
Description |
|---|---|---|---|---|
|
string |
“auto” |
yes |
Backend of cv::dnn: auto, cpu, opencl, opencl_fp16, cuda or cuda_fp16. auto uses CUDA when OpenCV is built with CUDA and a CUDA device is found, and the CPU otherwise. |
|
string |
“” |
yes |
Path or URL of the class names of the model, one name per line, the first one is the background, or empty for background and person of PP-HumanSeg |
|
int |
192 (1 - 4096) |
yes |
Height of the network input |
|
int |
192 (1 - 4096) |
yes |
Width of the network input |
|
double |
127.5 (0 - 255) |
yes |
Mean subtracted from the pixel values before the scale |
|
string |
“” |
yes |
Path or URL of the model whose output is the scores of the classes for each pixel, empty for PP-HumanSeg of opencv_zoo. The URL is downloaded to ~/.ros/opencv_apps/models/ at the first time |
|
int |
3 |
no, restart the node |
Specify queue_size of input image subscribers |
|
double |
0.00784313725490196 (0 - 1) |
yes |
Multiplier of the pixel values for the network input |
|
bool |
true |
yes |
Swap the red and blue channels, true for the models trained in RGB |
Source
src/nodelet/dnn_semantic_segmentation_nodelet.cpp, launch/dnn_semantic_segmentation.launch.xml